
Isolation
Being wrong is survivable, because a wrong attempt is disposable.

Agentic Data Engineering
It builds and maintains data pipelines on the platform you already run.

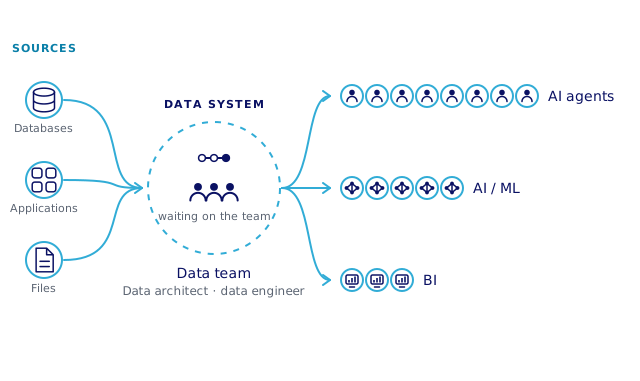
53% of a data engineer’s time goes to maintaining existing pipelines (Fivetran, 2026). An agent can take that load if it has somewhere to be wrong on real data that production never sees, and guardrails it cannot reason around.

Before building
It reads the repository and platform you already run and writes the context every stage reads: vocabulary, decisions, conventions. Agent Readiness findings follow, each with its evidence.
Before building
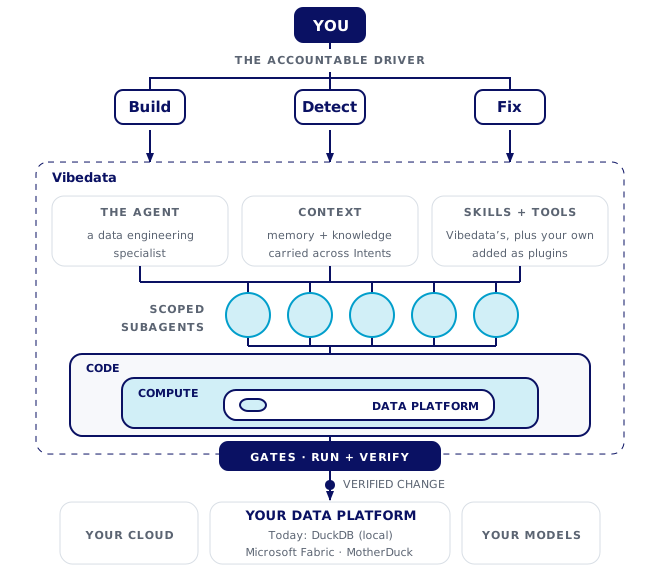
Every change gets its own branch and workspace, built natively on your platform. Production never sees it, so a wrong attempt is disposable and agents run side by side.
While building
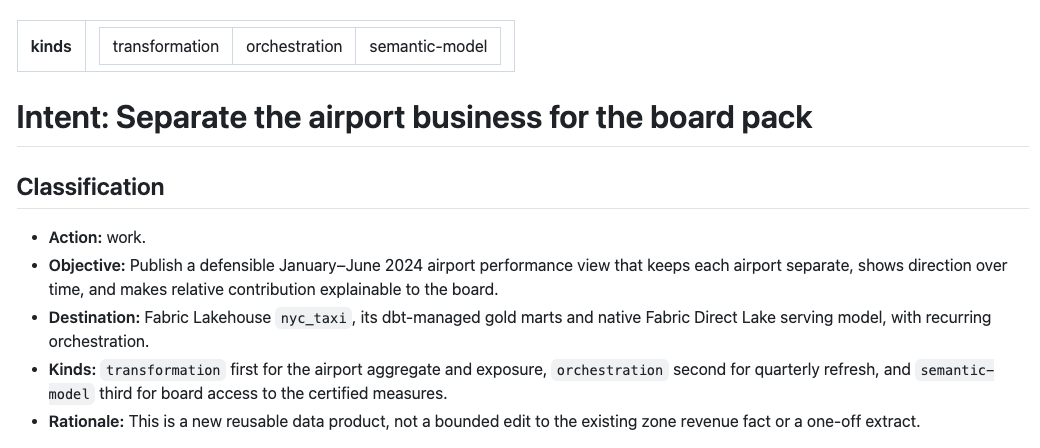
Vibedata takes the request to a spec you approve, then designs, plans and builds on subagents, unattended. It asks only what your code and marts leave open.
While testing
A gate runs the change against real data on your compute and records evidence per requirement. You read the evidence and the exceptions, then merge the pull request.
After release
Vibedata watches the platform, read-only, files what breaks as a GitHub Issue, and ships the fix as a pull request for a person to merge.
After release
The context Vibedata keeps on your estate answers questions in Vibedata, and grounds the agents your users already work in, with your grain, definitions and decisions.
Being wrong is survivable, because a wrong attempt is disposable.

Scoped to the data platform: schema changes, warehouse writes, and the deploy path.

Data engineering context: grain, freshness, and which mart the business reads.

The same loop, skills and gates on DuckDB, Microsoft Fabric and MotherDuck, built natively on each.
The same team ships five times more with Vibedata, once it changes what it focuses on and how it builds. We measure it as time to a pull request, and as the human time behind each accepted change.
Sign in with GitHub for the hosted sandbox, seeded on DuckDB. Or deploy from your cloud marketplace into your own subscription.
Vibedata is your data engineering agent. It builds and maintains data pipelines on the platform you already run, with the four things a general coding agent lacks for data work: isolation, guardrails, context and cross-platform. It covers the whole lifecycle: onboarding your estate, isolating and building each change, review and verify, keeping it running, and giving your agents context.
In your own cloud subscription, deployed from your cloud marketplace. There is no multi-tenant SaaS.
In production today: DuckDB, Microsoft Fabric and MotherDuck. Design partner open: Databricks and Redshift. Coming next: BigQuery, Oracle, Postgres and Snowflake.
There are two equal ways in: a hosted sandbox seeded on DuckDB that needs no install and no tenant setup, or a deployment from your cloud marketplace into your own subscription. Sandbox sign-in is through GitHub.
It reads metadata, code and execution traces, never your rows. Profiling and verification run as queries on your own compute. Agents act under scoped, short-lived credentials, with tamper-evident, immutable audit logging.